Library/GTM Vault Podcast 48
The Transcript Is the Commodity, the Context Is the Asset
Gorish Aggarwal spent 18 months building a context graph his better-funded competitors cannot copy, and now he says delete Gong

In 2023 the industry standard for revenue AI was to pass an entire call transcript into a language model and hope. Gorish Aggarwal tried it. It failed at producing something as basic as next steps unless you massaged the input first, feeding the model context about the output you wanted, the customer, and the deal. So he stopped treating the transcript as the product and started treating it as raw material. Six to eight months later the rest of the market was still dumping full transcripts into models and calling it AI.
That gap became the company. His read was that as models improve, the value of what you pass them improves faster than the models themselves. If that is true, the durable asset is not the model and it is not the recording. It is the structured understanding of your business that decides what gets passed in.
This is not an argument about transcription quality. It is an argument about which layer of the revenue stack is being repriced to zero, and Sybill spent eighteen months building the other layer while better-funded competitors shipped features.
Gorish Aggarwal is co-founder and CEO of Sybill. Sybill launched as an AI sales assistant for account executives, then spent eighteen months building an org-level context graph underneath it, a self-evolving layer connecting customers, team, and company process that updates daily from every new conversation. The bet was made with a fraction of the capital his category raised, which is the part that shaped the architecture rather than just the burn rate. Gorish now argues the next Cursor-scale company in GTM tech emerges from exactly this layer inside twelve to eighteen months, and he is explicit that he is building to be it.
In GTM 48, Gorish breaks down why passing the full transcript into a model was never the product, what a context layer actually means operationally across its three pillars, why Sybill shipped an MCP connector into Claude’s directory instead of defending its own dashboard, why incumbents cannot bolt a context layer onto platforms architected before language models existed, where agents with complete context still produce garbage, what identity resolution is quietly doing to every CRM in the market, and the single roadmap question that let a smaller team out-build the field for eighteen months.
This is not a conversation about note takers. It is a conversation about which half of your revenue stack is the commodity and which half is the asset, and what that means before your next renewal cycle.
Watch or listen now across YouTube, Apple Podcasts, Spotify, and X
Inside this episode
This episode maps the structural difference between recording what happened and understanding it, and what happens to a category when the first one becomes free.
Gorish opens with the 2023 realization. Passing a full transcript into a model did not work, and it failed in a specific way that mattered. Even getting usable next steps required feeding the model context about the desired output, the customer, and the deal alongside the raw text. The transcript was an input, not a signal. He assumed the market would catch on quickly. It did not. Six to eight months later the standard was still transcript in, output out. That lag is where the head start came from, and he is candid that he expected it to be much shorter.
We go deep on what a context layer means operationally, because the phrase has been diluted into meaninglessness over the last year. Gorish defines it as three pillars. Customers, meaning the prospects, accounts, and opportunities. Team, meaning every person from rep to CRO, their strengths, weaknesses, objectives, and preferences for how they work. Company process, meaning product lines, pricing, the objections that actually come back, market verticals, and the competitors you keep running into. Most revenue tools capture the first pillar and treat the other two as configuration. The graph only compounds when all three evolve daily against new conversations, and that daily evolution is the part that cannot be retrofitted.
We cover why he does not consider this a repositioning. Gorish pushes back on the framing directly. The technology moved and the product moved with it, and the visible change was that a second buyer appeared. Sybill started as an automation layer over an AE’s deals, helping one rep write a better follow-up and save time. As the org-level graph came together, the CRO and the VP of Sales became buyers of the same asset for entirely different reasons. He is honest that this made the offering muddier before it made it stronger.
We go into the MCP decision, which is the counterintuitive move in the episode. Most vendors Sybill’s size were building another dashboard. Sybill exposed its context layer through an MCP connector in Claude’s directory, then built an ingest MCP running the other direction so website data, Notion, Drive, and Slack flow in, get systematized against the graph, and become available downstream. Giving up the screen cost them depth of insight into how the work gets done. What they gained was a builder persona in RevOps creating agents on top of the layer, and those agents scale across an entire organization. One builder’s workflow becomes a thousand reps’ default. Gorish is clear that the interface still matters for a typical seller who wants the job done rather than a system to build, so this is a segmentation call rather than a religion.
We cover the demo that keeps closing deals, which is not a demo of Sybill. It is running Claude twice against the same deals and the same calls, once with the Ask Sybill MCP connected and once without. The delta in output is the pitch. Nothing about that comparison requires the buyer to trust a vendor claim, which is why Gorish reports MCP usage skyrocketing past what he predicted.
We go into personal agents versus GTM agents and where they collide, which is the architecture question most teams have not thought about yet. Gorish runs five personal agents through an OpenClaw setup covering fundraising, people ops, GTM, product, and a personal assistant he calls Dobby. A personal agent knows his preferences and his relationships, so a LinkedIn message referencing this podcast gets connected to this conversation without being told. A GTM agent is organizational. It knows process, product lines, pricing, and objections, it ingests data sources that actively compete with each other, and it scales across hundreds or thousands of reps. His resolution of the ownership fight is the useful part. The company’s benefit is that no knowledge walks out the door when a strong rep leaves. The individual’s benefit is a preference layer they carry from company A to company B. No sane org graph imports a single rep’s perspective. It triangulates across fifteen to fifty and picks the best pattern per domain.
We cover the honest failure mode, and it is not the one people expect. Give an agent all the context in the world and it still fails at creativity. Genuinely novel choices, the strategic decision unique to this deal in this organization, remain human work. Gorish points at the LinkedIn auto-commenter era as the market learning this in public. Everything templated or close to templated, agents handle. The line sits exactly where critical thinking begins.
We go into why incumbents cannot ship this as a feature, and Gorish gets specific about architecture rather than hand-waving about innovator’s dilemma. Revenue platforms were designed before language models existed. Their data pipelines, storage models, indexing strategies, and application architecture were all optimized for capturing structured data and querying it. Continuously connecting people, conversations, emails, meetings, CRM changes, and outcomes into a living model of how a company wins is a different problem needing a different foundation. His image for the retrofit: replacing a skyscraper’s foundation while millions of customers are still inside it, working.
We cover identity resolution, the unglamorous thing actually breaking the CRM. Rick Koleta on LinkedIn, Rick K in email, RK in the CRM. If an agent cannot collapse those into one node, it does not know where to look before it acts. The same failure runs through internal meetings, where a single pipeline review covers twenty to thirty deals, each carrying real decisions about discounts, MSA terms, and next steps, and most tools cannot attribute what was said to which deal. Slack is worse, a firehose with no labels and no reliable classification, where nobody tags the account record when they mention a customer. Agents bolted onto that data inherit every fragment of it.
We go into Sybill’s own stack, which is the part operators will want. They run their entire sales process on it: forecast calls, coaching, deal execution, follow-up, dashboards, decks, and proposals. Marketing and product use it to read what messaging is landing and where the product gaps are. The interesting build is the in-house signals engine, made after evaluating the well-known tools in the space and finding nothing that did the job. Watchers run across LinkedIn and Slack communities to see who is talking about what, output flows into a master list with enrichment and joining, and records connect by the actual LinkedIn identifiers rather than the canonical ones. The result tracks a single person across Slack, a Pavilion community, LinkedIn, and internal context, with news layered on top. Gorish notes in passing that the message which booked this podcast carried his agent’s fingerprints.
We close on capital discipline and the rapid fire. Sybill did not go wide early, and Gorish is blunt that doing so would have failed epically. Every roadmap item had to clear one question. Then the rapid fire compresses the entire thesis: the metric that deserves more attention is win rates, the most overrated capability in revenue AI is note taking, the thing a founder should delete from their stack today is Gong, and in three years the CRM is a database.
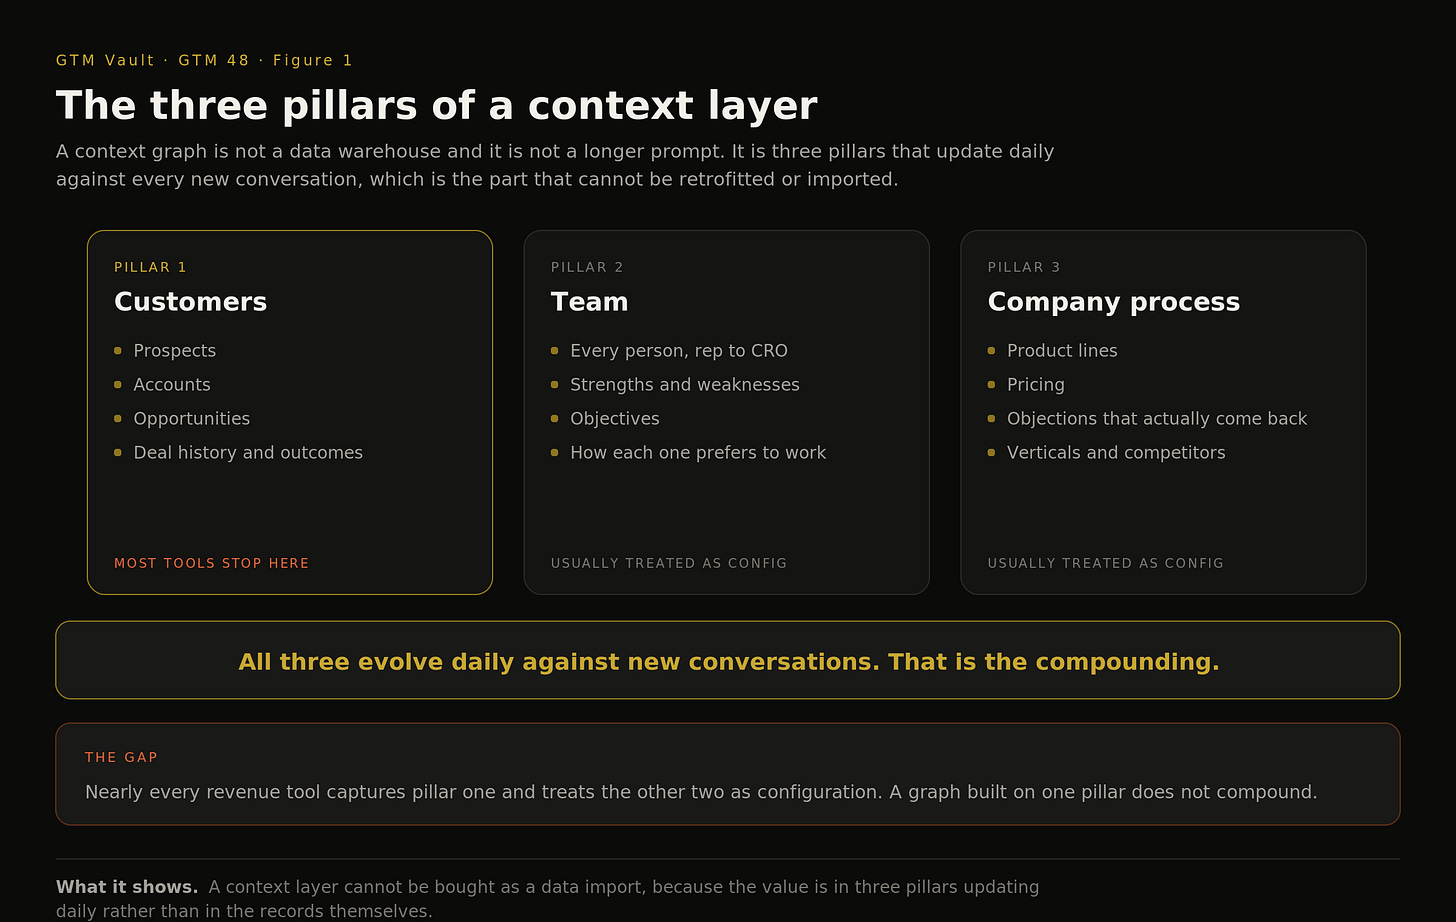
Figure 1. The three pillars of a context layer. Customers, team, and company process, all updating daily against new conversations. Nearly every revenue tool captures the first and treats the other two as configuration, which is why a graph built on one pillar does not compound.
Discussed in this episode
(0:00) The Bet: Transcript Is the Commodity, Context Is the Asset
(4:50) What a Context Layer Means: The Three Pillars
(5:53) The MCP Connector Bet: Distribution Over Dashboard
(8:55) Personal Agents vs GTM Agents
(12:10) Failure Modes and Category Casualties
(15:40) Why Incumbents Cannot Bolt This On
(17:26) What Breaks When Agents Run on Stale CRM
(19:19) Inside Sybill's Own Stack
(22:20) Capital Discipline and the Roadmap Question
(25:02) The 2028 Picture and Rapid Fire
Key takeaways
1. The transcript was never the product, and the market took eight months to notice.
Even in 2023, getting usable next steps out of a model required feeding it context about the desired output, the customer, and the deal. The raw text alone produced nothing worth sending. The inversion underneath this is the load-bearing idea in the episode: as models improve, the value of what you pass them improves faster than the models themselves. That makes the model the commodity and the input the asset, which is the opposite of how most revenue AI is priced today.
2. A context layer has three pillars, and most tools touch one.
Customers, meaning prospects, accounts, and opportunities. Team, meaning every person’s strengths, weaknesses, objectives, and working preferences from rep to CRO. Company process, meaning product lines, pricing, real objections, verticals, and competition. Nearly every revenue tool in the market captures the first pillar and treats the other two as configuration. The graph only compounds when all three update daily against new conversations, which is why this cannot be bought as a data import.
3. Identity resolution is the unglamorous failure quietly breaking every CRM.
Rick Koleta on LinkedIn, Rick K in email, RK in the CRM. If the agent cannot collapse those into a single node, it does not know where to look before acting, and it will act on a fraction of what the company knows. The same fragmentation runs through internal meetings, where one pipeline review covers twenty to thirty deals with real decisions inside each, and through Slack, where a firehose of relevant context arrives with no labels and no consistent account references. Every agent deployed on top of that data inherits the fragmentation and produces confident, partial answers.
4. Distribution through the agent layer beat defending the dashboard.
Sybill exposed its context layer through MCP rather than forcing usage through its own screen, and adoption grew faster than Gorish predicted for a reason he did not anticipate. RevOps builders create agents on top of the layer, and those agents scale across the whole organization. One builder’s workflow becomes a thousand reps’ default. The vendor gives up depth of insight into how the work is done and gains a distribution surface it did not have to build. The screen was never the moat.
5. Incumbents cannot bolt on a context layer, because it is a foundation and not a feature.
Revenue platforms were architected before language models existed, with pipelines, storage, and indexing optimized for structured capture and query. Continuously connecting people, conversations, emails, CRM changes, and outcomes into a living model of how a company wins is a different problem requiring a different foundation. Gorish’s image is a skyscraper whose foundation has to be replaced while millions of customers are still inside working. This is the strongest argument in the episode for why a startup owns this layer, and it is architectural rather than cultural.
6. One roadmap question enforced eighteen months of discipline.
Every feature request, and there were many, including a forecasting module, a coaching module, a performance dashboard, and a deal room, had to answer two things. Does this help the context graph learn, and does it compound the intelligence already built. Two nos meant not built. That is capital discipline expressed as architecture rather than as a spending cap, and Gorish credits it directly with surviving where wider, shallower competitors stalled.
Frameworks from the episode
1. The context graph
A self-evolving information layer built on three pillars: customers, team, and company process. It ingests conversations, emails, meetings, and CRM changes daily, resolves identities across every surface a person appears on, and outputs the context an agent needs to act without a human feeding it instructions each time. The test for what belongs in it is the same test Sybill uses on its roadmap: does this input help the graph learn, and does it compound what the graph already knows. The measured output Gorish reports is a 95 percent reduction in the human actions required to produce a single follow-up email.
2. The roadmap question as capital allocation
For a company with a fraction of its category’s funding, the constraint is not what to build, it is what to refuse. Sybill’s filter was one question applied to every request: does this help the context graph learn and does it compound existing intelligence. Feature parity with better-funded competitors was never the goal, so the requests that would have consumed the eighteen months, the forecasting module and the coaching module and the deal room, were declined. The output is a company with one deep asset instead of six shallow ones, and a foundation that is now the thing being scaled rather than the thing being rebuilt.
3. The org layer and the personal layer
Two graphs with a deliberate boundary between them. The org graph holds process, product, pricing, and objection handling, triangulated across fifteen to fifty reps rather than imported from any single one, which is how knowledge stops walking out the door when a strong rep leaves. The personal layer sits on top and holds an individual’s preferences, relationships, and working style, and it travels with them from company A to company B. The architecture question is not who owns the context. It is where that boundary sits, and most teams have not yet asked it.
What to do this week
-
Run the with-and-without test on your own data
Ask your AI assistant one real deal question using CRM data alone, then ask it again with calls, email, and Slack context connected. This is the comparison Sybill runs in sales conversations, and it works because it requires no vendor claim. The gap between the two outputs is the size of your context problem, measured before you spend anything on solving it.
-
Count your identity fragments
Pick ten active deals and count how many name variants each buyer has across the CRM, email, LinkedIn, and Slack. Then check whether any system in your stack collapses them into one record. Every unresolved variant is a place where an agent will act on partial information and report it as complete.
-
Apply the roadmap question to your stack, not just your roadmap
For every tool you pay for, ask whether it makes your account context compound or whether it records activity. Recording is available from Zoom, free from Fathom, and bundled into a dozen tools already on your laptop. Per this episode, the recorders are the commodity layer and the first candidates for deletion at renewal.
-
Audit one internal pipeline review for lost context
Take the recording of your last forecast or pipeline call, list every deal discussed, and check what made it into the CRM against the right record. The decisions inside those meetings, on discounts, on MSA terms, on next steps, are the richest context your company produces and the least likely to be captured correctly. Whatever is missing is what your agents will not know.
Why this matters
Every tool in your revenue stack does one of two things. It records what happened, or it compounds what your company understands. For most of the last decade the distinction did not matter, because recording was expensive and understanding was a human job performed on top of the record. Gong built a multi-billion dollar company in that world, and it was the right company to build.
The market has repriced the first half. Recording comes with Zoom, is given away by Fathom, and is bundled into a dozen tools already running on the laptop. When a capability is free at every price point, the value does not disappear. It moves. It moves to whoever can take the recording, resolve who is being referenced across fifteen surfaces, connect it to what was said in Slack two months ago, and hand an agent enough context to act without a human writing the instructions.
That is a different piece of software than the one most revenue teams bought. It cannot be assembled from a data import, because the pillars have to evolve daily against new conversations. It cannot be shipped as a feature by a platform architected before language models existed, because the pipelines, storage, and indexing were optimized for structured capture rather than continuous learning. And it cannot be solved with a longer context window, because the failure is not capacity. The failure is that the model does not know Rick Koleta and RK are the same person.
The teams that feel this first are the ones deploying agents on top of a CRM they already know is fragmented. The agent will be confident and it will be wrong, and the fragmentation will get blamed on the model. The teams that feel it second are the ones paying for four tools that record and none that compound.
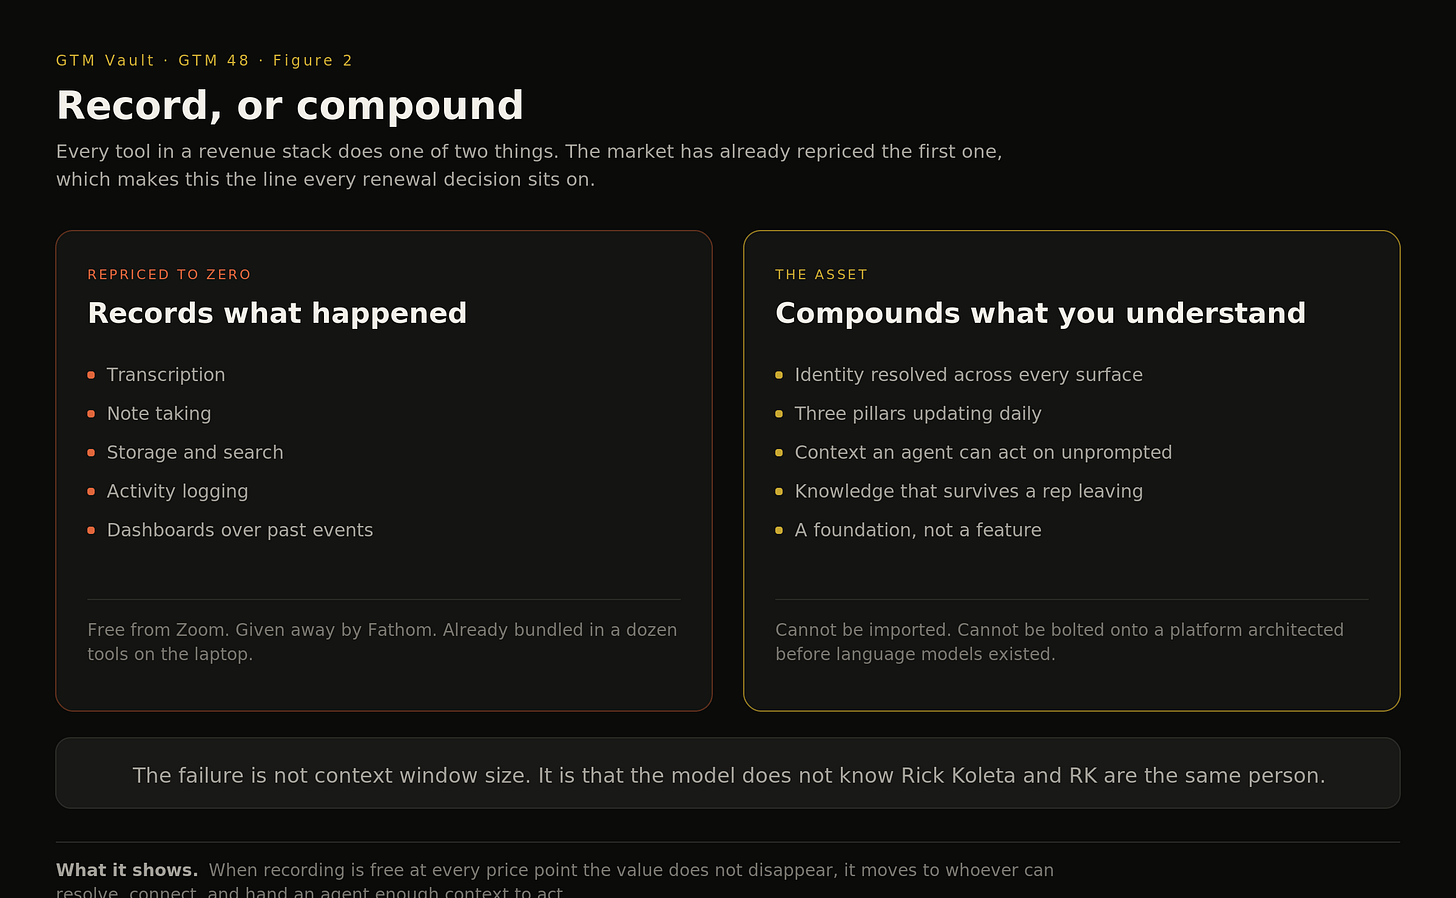
Figure 2. Record, or compound. Recording is free at every price point now, so the value moved to whoever can resolve identity across surfaces and hand an agent context it can act on. This is the line every renewal decision sits on.
Before your next renewal cycle, know which side of that line each line item sits on.
This is GTM Vault.
If this changed how you read your own stack, send it to whoever signs the renewals.
Connect
Follow Gorish Aggarwal // Sybill
Follow Rick Koleta // GTM Vault
Thanks for listening. See you in the next episode.
P.S. Annual paid subscribers get a Private GTM Blueprint Session. One working session to identify your primary GTM constraint and design the 90-day architecture to resolve it.
Full transcript
Machine-generated transcript from the episode video. Speaker labels are not included and some names and product terms may be transcribed phonetically.
[0:00] If you have a context layer versus if you don't have a context layer, the output is just significantly different. The market industry standard was still you pass the entire transcript into an LLM to get an output, which doesn't really work. I think people just misunderstand how hard this transaction act plays. You need to divide and figure out specifically. Meet Gorish Agarwal, CEO of Cibil. He scaled his platform from $100,000 to $1 million ARR in just 9 months. While legacy tools built glorified notetakers, Gorish built a true context engine turning raw conversations into living data that puts revenue execution on autopilot.
[0:41] Most agents, most CRM, most tools in fact are not able to understand what's going on within those meetings to take an action which is contextual. Most incumbents can think of adding a context layer as another feature, but that's not how this architecture works. If you think about revenue platforms, they were designed before LLM even existed. If your platform is not built to continuously connect people, conversation, emails, meetings, CRM changes, outcomes into a living, breathing understanding of how a company is winning. You cannot just bolt that on on top of a base platform. It's like replacing a skyscraper while people are still inside it and actively working inside it. My goal is to build revenue to such a point where revenue can run on autopilot and we're getting to a stage where 12 to 18 months from now we'll see.
[1:38] Welcome to GTM Vault. Gores Agarwal runs Cibil which has spent the last year arguing that in revenue AI the transcript is the commodity and the context is the asset. That is the bet I want to pressure test today. So let me start where it started. Cibil launched as an AI sales assistant. Walk me through the moment you realized the transcript was the commodity and the context was the asset. Thanks Rick. Yeah, I think we started using transcript more as just an input in the year of 2023. I think one of the big things we realized is with LLMs at that time the models were still very very basic and so passing the full transcript to the LLM was not just useful even to get next steps you had to do a lot of massaging in order to get to the next steps. And one of the things we used to
[2:41] do was pass in context about the output that we're looking for and the information that we started sending out to the customers. So once we learned that and we actually were thinking we had this idea that people would catch on to that very very quickly. But what we ended up realizing was 6 8 months later the market industry standard was still you pass the entire transcript into an LLM to get it which doesn't really work. I think that's where we realize context and what gets passed on specific information points is really critical because even as the models were improving the information that you might want to process itself improves further alongside that. So that's where we started to build an org level context graph. We started with the deals first and then over time included the team and the company process.
[3:30] So repositioning a company mid-flight is expensive. What did you have to stop selling and who did you lose by changing this story? I don't think we repositioned it per se. It was more that the technology evolved a lot and then we started talking about this context of context graph which was which was not very common at the time. These days you'll find a lot of companies talking about context graph but 12 18 months earlier there was pretty much no one that had no that had known or understood the concept at all. So for us it was more about okay how do we educate the market about this shift that's happening and the need of the shift and the second thing we also realized and this was a very plus sign for us is we were very focused on getting the AES and automation layer over their deals. So how can I help the AE write better follow-up save their time win more deals over time we realized as we are building this or level context drop we had another buyer persona namely the CRO and the VP sales who could really get a ton of value out of this so it was it helped us expand our offering in the zone also making it
[4:34] slightly muddier because earlier you used to be just for the A and then you have the CR and the VP of sales on on top so but it helped expand the offering overall into what we are proving Yeah, I can see how now you're targeting you're gliding up market or up to the decision makers. And so define what context layer for revenue teams means operationally. It's basically a self- evvolving information layer which captures different aspects of the business that you're trying to optimize on. So for a revenue team and specifically for a sales team, it means the customers themselves which is who are the prospects, the accounts, the opportunities for the re. So that's the first pillar. The second pillar is your team. So from the rep to the CRO, what are everyone's strengths, weaknesses, what are their objectives and also how do they like to do certain things like their preferences? And the third pillar is your company processes. So product lines, pricing, objections that are received in a sales context, your market vertical, what kind of competitions are
[5:37] you coming against, that itself is also a big piece within a sales context. And if you can help that have that evolving in part of like as part of a system on a daily basis with new conversations coming in that forms the context craft you ship the civil MCP connector into cloud's directory earlier this year most vendors your size were still building dashboards what convinced you to distribute through the agent service instead of your own interface we don't discriminate between like where people get to use civil what we what we saw was in the market there was a need especially for the builder revops persona where they wanted to build their own agents on top of the context layer and the raw data that we capture. So we decided to expose that as part of the civil mcp. We actually also have an ingest MCP where we can ingest any other surface or data source into civil and then contextualize it with respect to the context graph. So think of website data, document data from notion or drive or slack. Everything flows into civil.
[6:40] It gets systematized and organized in that context layer and then people are able to access it downstream. When when your product lives inside cloud or any assisting you give up the screen, what do you gain that is worth losing the surface where you use to control the experience? For us, the surface is only as valuable as the user user need and the user adoption. So what we are seeing is that this specifically this builder persona loves to build agents and automations on top of the context layer and that's what they get out of SEL. Now what we what we gain is very interesting newer use cases that people have started building on top of SEL. What we have lost is obviously deeper information on those use cases.
[7:25] This is how still true only for a segment of our user base. If you think about a typical seller, they are not trying to build their own agents. They want to get the job done as soon as possible. And that is still where software interfaces, vertical software interfaces are still extremely What did he learn in the first 90 days of MCP usage that surprised you? What are people actually doing with it? H I think honestly like what people were able to see extremely clearly with MCP was what it the outputs which were possible with having a context layer as part of the introduction as part of the in input to your claude versus if you have a context layer versus if you don't have a context layer the output is just significantly different and what I mean by that is it's just you could actually run claude with and without the askible MCP and in one case you have your let's say your deals and opportunities via HubSpot or headless Salesforce automations and then you also have your calls via something like cy or gongs API but then on the other side you have the
[8:29] MCP control and people just love to see how much of a difference that makes between the output that you're getting the other thing which we were honestly blown about why was the level of usage of MCP has skyrocketed because your revops has built agents which are on top of these MCP outcomes which can scale across an entire organization. I think that has been pretty interesting to see as well. You wanted to go deep on personal and GTM agents. Draw the line for me. What does a personal agent do for a single AE that a team level GTM agent can't cannot and where where do they collide? So a personal agent is one that understands my personal preferences. So I built a lot of personal agents. I have open claw running on my system which is separate from my sales agent. And as part of that open clause setup, I have actually five different agents that are working for me. One on the fundraiser side, one on the people op side, a third one on the GTM, and then we have a product agent and a personal literally a Dobby which is doing all of my personal stuff. That these set of personal agents
[9:34] understand my preferences, understand who I know in my day-to-day basis, what are the context of those people. Like for example, this conversation I know now Rick is the founder of G GTM vault. we had a podcast. So let's say you send me an email or a LinkedIn message a few days later. Hey, here's a podcast recording. The personal agent would know what that connects to. It understands that. It's able to link all up. A GTM agent on the other hand is more of an organizational GTM organizational agent. So it understands yes to some extent an individual person's preferences but primarily it understands what is the organization's process what are the product lines what are the pricing what kind of objections we come across and that's a much more interesting agent because you have a lot of data sources many of them actually competing against each other that are coming in to update this internal agent context like agent context and that becomes tricky to both implement but also So you can scale it across hundreds or thousands of reps and people.
[10:35] The personal agent needs my contacts, my deals, my calls, my writing style. The company wants the context owned at the team level. Who wins the fight? And what does the architecture look like when both need to read from the same graph? So the company's benefit is that no knowledge will walk out of the door when a single awesome rep leaves the company. Right? the rep's successful like object approaches, their objections that they navigated, the patterns that they discovered, all of that becomes part of an organization sales process. At the same time, for an individual person, they get to build their own preference within their context craft and so they don't have to start from like one they don't have to start from scratch because they have the organization's context craft gets layered in to their own preferences. But then they can personalize it on a daily basis as they work with their style with their preferences. Now in terms of who wins the fight, it's it's dependent on different aspects. No company or GTM agent wants to single-handedly import
[11:39] just a single rep's perspective. It should ideally be smart enough to capture context from 15 different or 50 different reps and figure out the best one in different domains and then use that as the starting point. For an personal agent, it's much more about hey these are my personal preferences and I can actually take those personal preferences when I even shift from organization A to organization B. And so there is a merging of the two but also there's a layer of boundary between them. Give me the honest failure modes. What have you watched a Where have you watched agents with full context still produce garbage and what was missing? Creativity. Agents are really not great at creativity and building creative output. And I think what ends up happening with agents is you can give it all the context in the world but when it comes to making a choice which is very new choice, it may still fail as an agent. We saw this a lot with LinkedIn
[12:41] commenting agents. There was a time where everyone was using a commenter auto commenter on LinkedIn. We thankfully are now past that like but basically agents do not know how to creatively draft and create content which I think is still a very humanesque job that applies to sales because you have to make strategic decisions which are truly unique in the organization and that's where you need your critical thinking as well as like understanding of the deal process everything baseline the agents are able to do everything templated or close enough to template the agents are able Here's the uncomfortable version of your own thesis if the winner in revenue AI owns the unified context graph. What happens to every standalone tool built on transcription? Name the category casualties.
[13:28] I think there are two kinds of casualties that we are seeing in the market today. So one set is people that have failed to innovate quickly. Market and AI landscape has shifted and that segment of the market has been more than they've been trying to find out their ground. There is another segment of the market which is they have built an awesome product or an awesome tech and IP and what they have not been able to crack is distribution which is again a very critical piece in the entire stack. So for those companies those are the other set of casualties and we see that there are many acquisitions happening in this market with especially the GTM tech market is really hot right now with G Zoom, HubSpot, Apollo acquiring multiple players in order to build out their own product thesis and as a result trying to get some of that early startup native native AI company talent in the companies.
[14:24] Gong built a multi-billion dollar company on the recording. Fathom gave it away for free. What does the value actually settle when recording is a commodity at every price point? Recording is you can get recording by Zoom. The function is can you get can you take the recording and can you ingest it, index it and then ingest it into the AI agents that you're trying to build on top. So we could I could have a conversation with you. We could get a recording by 15 different tools which are on our laptops right now. The having just the transcript alone does not help. understanding what actually is being said on the transcript, who is being referenced to like we start talking about John, John Doe, who is John Doe, how does that connect to previous people that I've spoken to, what are the other folks in my like when I discussed John Doe in the Slack in past, those are where those connections are where the relationships start becoming richer.
[15:13] That is what a typically human is expected to do even today which is pretty redundant because if an agent can make those connections about John Doe across 15 different surfaces I think that's a very powerful that's that's where the majority of quality information lies. That's what makes the process more autonomous versus a human will like or we will continue to have to give instructions to the agent. Otherwise, what stops model what stops the model providers themselves or the CRM incumbents from absorbing the context layer? Salesforce would say agent force this is exactly this. Why is a startup the right owner? I think people just misunderstand like how hard this transaction actually is.
[15:58] Like most incumbents can think of adding a context layer as another feature but that's not how this architecture works. Like if you think about revenue platforms they were designed before LLM even existed. So the data pipelines, the storage model, the indexing strategies, the application architecture were all optimized for capturing data and querying the data in a very structured fashion. And because that's what they really needed to do, right? Learning from the data and learning from the interactions and activity is a fundamentally very different problem. So if your platform is not built to continuously connect people, conversation, emails, meetings, CRM changes, outcomes into a living breathing understanding of how a company is winning. Like you cannot just bolt that on on top of a like base platform.
[16:47] You're basically building like the foundation that your customers, millions of customers in some cases are already actively working in it, right? It's like replacing a skyscraper while people are still, you know, inside it and actively working inside it. We had this advantage where we were very early to understanding how LLMs are actually functioning and we could ask ourselves if an AI needs to reason over revenue data, what should that foundation even look like? If AI needs to be autonomous, what should that look like? And that leads to a very different architecture than the software that's primarily designed for reporting and analytics. That's right. My sequencing essay argues step one of AI native GTM is eliminating the manual CRM update hop. And Cibil's positioning is literally that CRM updates itself from the calls. Walk me through what breaks in companies that skip this step and bulk agents on top of stale data. If I meet you on LinkedIn and then I meet you over email and then we are doing this podcast. If your name
[17:51] in all three places is Rick Ka Rick K RK and then an agent is not able to combine all three of those into a single hop. Then if I have to take an action with respect to URI then my agent does not know which of the three or one or all of the three does it need to go to to get that data. That's what is primarily broken across your CRM today. This happens a very simple example where we see this very frequently is internal meetings. You have sales rep discussing with your managers in a single meeting which will comprise of 20 to 30 different deals. Now each of those deals has very rich context because you have just taken a decision as to whether we give this discount, whether we agree to these MSA terms, whether we what's the next step that we should be taking. Most agents, most CRM, most tools in fact are not able to understand what's going on within those meetings to take an action which is contextual. You need to divide and figure out specifically within an internal meeting what exactly is going
[18:53] on per deal to make a contextual agent. That's what is missing with a lot of tech. We see that with internal data. We see that with in-person recordings. Slack is another one which is like a fire hose of data with no labels, no perfect classification. People don't always index the CRM companies when they're talking about some individual in Slack and that's really critical to for an agent to act upon it. What does Cibil's own internal GTM stack look like? Do you run your own context layer on your own pipeline? And what has it changed about how you sell? Absolutely. So we use cible for our entire sales process. We do all of our forecast calls, our coaching, our like reps getting deal coaching. We are running entirety of deal execution through civil. So that includes not just following up over email but also creating dashboards, creating decks, creating proposals right on top of civil. We actually also have our marketing team and product team using civil quite a bit to understand what's
[19:56] what's like what's the messaging that's resonating with the market what is the market saying about certain things and then also to understand what are the gaps and requirements from a customer standpoint in the product today right so a lot of the sales conversational sales interaction stuff happens simply via seel itself and honestly it's made information exchange very easy because no one really needs to ask another person. It's all there and you can actually build dashboards on top of everything that's there. For our marketing, we are building our in-house grown signals engine after having queried a lot of tools within the space and we are becoming very successful at capturing some of the really nice in-house signals into a single pane of glass.
[20:42] Yeah. Like what kind of signals? So for instance, we now have watchers running across an entire LinkedIn and Slack communities to understand which people are talking about which topics and then we have a master gigal list. Think of it as context trap but for the marketing domain we didn't find anything available online. And we tried quite a few very well-known tools in the space. But we have watches running across a lot of social media spaces. And then we have enrichment and joining to build a master list of everything that comes everything that happens on those interfaces. And it's connected via LinkedIn IDs, not the canonical ones, the actual identifiers that LinkedIn uses. And then we are able to act on top of those signals because I can track Rick across Slack. I can track them across a pavilion community, across LinkedIn, across my own internal context and if there is any news that adds on top. So that has become a very big powerhouse of source of information then we run agents on top.
[21:40] Yeah, that sounds pretty powerful. I run a similar similar setup on on claude few different rails doing a similar approach but very rudimentary compared to what you just described. There's no ID tracking, for example. Yeah. Yeah. So, for example, the the message that helped set up this podcast had my agent's fingerprints as part of the message. So, the followup like like my calendar integration, the follow-ups, if you text me on LinkedIn right now, you might have an agent respond back with very relevant context about this podcast. I love it. You made this bet with a fraction of the funding your category competitors raised. How does capital discipline change with architectural bets you can afford to make?
[22:30] We didn't go very wide very soon all too quickly. There are a few players in the space that are trying to cap be trying to capture everything all at once and I think that doesn't work. I'm glad that we didn't do that and that didn't that would have failed epically for us because I think you first need to put in the right foundations of the system in place and the AI landscape have evolved quickly that the right foundations have been very critical. If we had grown, if we had started building like I need a forecasting module, we got so many requests early days where like people wanted a forecasting model and the coaching module and the performance tracking dashboard and a deal room and whatnot that I feel would have changed how the company trajectory would have been. But now that the foundation is put in place, now it's all about scaling. So we are like we are going after large amount of capital allocation both on the product side to build more surfaces to build more integrations because we can literally think of any data source on earth with some kind of an API or MCP connection which has customer data. We
[23:34] can feed that to power this context graph across the entire GTM and then use that downstream to run agents on top. So my goal is to build revenue to such a point where revenue can run on autopilot and we're getting to a stage where 12 to 18 months from now we'll see cursor like company emerge in the entire GTM tech space and I am betting on the fact that that company is I want I want to dive deeper into the that bet you're making the trajectory I know you you mentioned that it wasn't as much a reposition but perhaps more of an evolution. Can you talk about the how this affected the hiring the road map? What you say no to now that you didn't beforehand?
[24:17] So we didn't chase feature parity with the big tools in the market. That was I think the biggest shift that happened because of this capital discipline for us. Everything that was on the road map had a single question that needed to be answered for that thing to be on the road map, which was can this feature or this new integration or whatever help the context graph learn and does it compound the intelligence that it already has built out. And if if those two were not the case, then we would like typically not build that feature. And that was very like it took us 18 months to get the context layer to the place it is. And now it's like time to really scale up both the input and the output layer of that context.
[25:02] Paint the 2028 picture. A revenue team of what size running what agents and on what context. What does the human actually do all day? Okay. So I don't think the challenge is automation. I think where humans will create value is helping understand the question behind the question and creatively think of a way to solve that problem. And sales reps are unique because they will also on top have to build a relationship while solving the problem because trust is everything. You cannot do you cannot trust an AI to do something or buy buy from a AI directly. So in my world view everything that is outside of these three aspects solving like understanding what the problem is trying to find a creative solution to that problem if needed and then building trust and relationship. Everything outside of these three pieces your I and your agents and your entire software stack and processes should be able to capture. So think of SMB or midmarket deal where there is not a lot of creativity. That simply means that you will be taking conversations more like a
[26:04] support agent. You probably will have a live agent running on the side to tell you what what are the topics to be discussed in any point in the call and what how do we handle objections during the conversation and a bunch of other things. If you think about an enterprise deal, that's where humans add a lot more value because you have to be creative about who to target, how to target, and which pathways to go through and it's not just a very cut and dry process. What has to be true in 18 months for the context layer bet to be provably right and what would tell you it was I think the context layer is turning out to be right. The amount of actions that a human needs to do in order to get a single response even a single follow-up email is like we have seen it's 95% lower than if you were to use without anything without a context layer. It's only a question of what form shape form and shape that context layer will take and how expansive can that be. Can you make a context layer for sales and marketing combined or do you need both of them separate? Can you make a context layer for the entire company which is
[27:07] GTM people your product or are those three categories itself separate like those are questions we will be answering it's not about whether you need a context layer and whether that will be required got it all right now in one sentence first instinct one GTM metric that deserves more attention this year I think win rates is still something which is which is very lacking people are focusing on pipeline more and more and productivity I think win rates is what makes a big difference the most overrated capability in revenue AI right now. A lot of note takingaking I think is still very out there in the market and very useless. One thing a founder should delete from their sales stack today. I'd say gong a habit or mental model that shapes how you build.
[27:52] I think you need to learn how to manage AI as a person. It's a very underrated skill on managing agents and as a result also managing humans. Complete the sentence. in 3 years. The CRM is a database. That is Gorish Agarwal, CEO of Sibil. If you want to see the context layer, he has been describing. Cibil is at sbill.ai and Gorish is worth following on LinkedIn for the vendor side read on where revenue AI is going. If this one gave you a sharper way to think about your own stack, subscribe to GTM Vault, where 26,000 plus founders and revenue leaders work through exactly these architecture questions. Thanks for listening.
[28:33] Thank you so much.